Model dossier · preview · read 2026-11-13
Qwen4-Max-Preview: a 1M-token flagship with a 14-day clock
Short answer
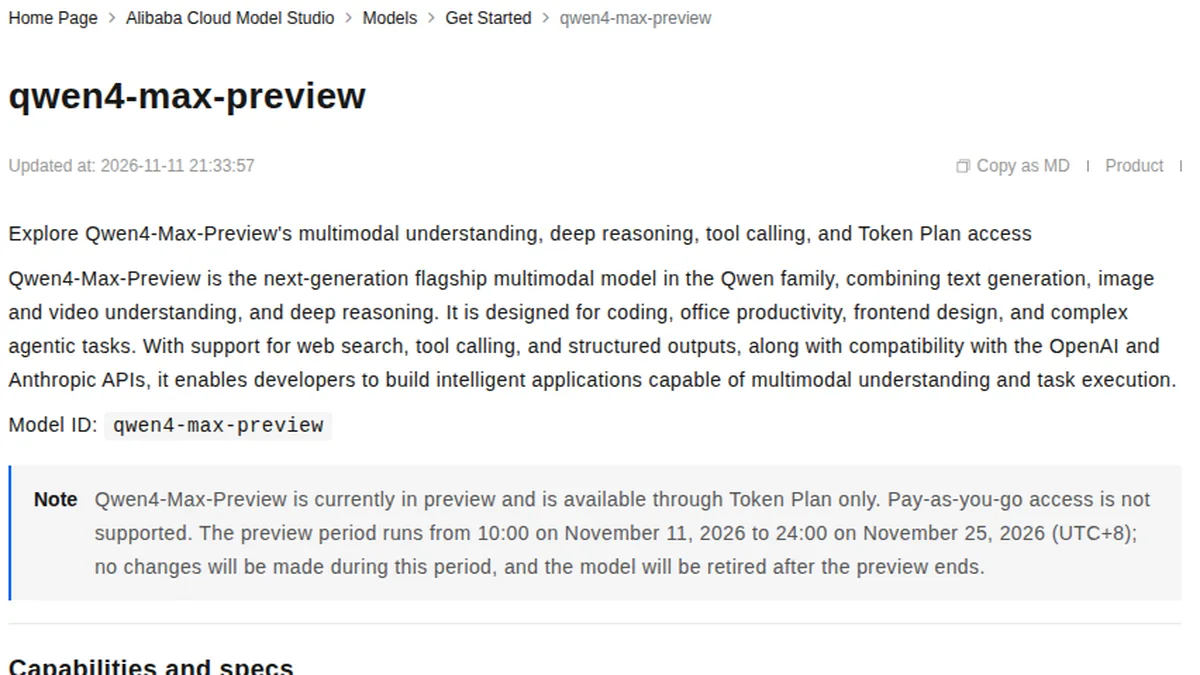
Qwen4-Max-Preview is Alibaba's time-limited Qwen4 flagship. It accepts text, images and video, supports deep reasoning and tool calling, and pairs a 1M-token context with 393,216 output tokens shared by thinking and the answer. The catch is access: it runs only through Token Plan, not pay-as-you-go, and the official preview ends on 2026-11-25.
Released 2026-11-11 Retires 2026-11-25 Alibaba model page →
- 1Mcontext tokens
- 393Koutput tokens
- $6Token Plan from / month
- Nov 25preview retirement
The constraint that changes the decision
- Token Plan is not pay-as-you-go. It is a monthly Credits subscription.
- The personal plan has a usage scope. Alibaba says it is for interactive use inside coding and agent tools, not production backends or automation scripts.
- The model is temporary. The preview retires on 2026-11-25; do not build an unhedged production dependency on it.
The 14-day clock
| Date | What happens | What to do |
|---|---|---|
| 2026-11-11 | Preview opens at 10:00 UTC+8. | Read the model page and decide whether a Token Plan evaluation is worth the subscription. |
| 2026-11-25 | Preview ends at 24:00 UTC+8 and the model is retired. | Keep a dated result set. Do not assume the same model ID or price survives. |
A preview model is a moving target by definition. Alibaba says there will be no changes during the window, which makes the dates useful: a benchmark or cost test run inside the window describes a stable endpoint, but not a permanent product.
What Qwen4-Max-Preview actually is
Alibaba positions the model for coding, office productivity, frontend design and complex agentic tasks. The useful distinction is not “Qwen4” as a branding exercise. It is the combination of three capabilities in one preview endpoint: long context, a very large output budget, and visual input that accepts images and video.
The output ceiling matters because reasoning tokens spend from the same budget as the answer. A 393,216-token maximum does not mean every request returns a 393K answer. It means an agent can spend a long time thinking, calling tools and producing a final artifact before it hits the cap. That is a different operating profile from a chat model with a standard 8K or 32K completion limit.
Structured outputs, web search and tool calling make the page relevant to coding and agent workflows rather than to a single-turn chat demo. The OpenAI and Anthropic protocol compatibility lowers the integration cost for teams already using either request shape, but it does not change the Token Plan billing boundary.
Specs and API details
| Field | Value |
|---|---|
| Status | Preview 2026-11-11 10:00 to 2026-11-25 24:00 UTC+8; retired after the preview. |
| Model ID | qwen4-max-preview Alias: qwen4.0-max-preview. Both work; billing shows the alias. |
| Context | 1,000,000 tokens 1M-token input window. |
| Max output | 393,216 tokens Shared by reasoning and the final answer. |
| Input | Text, images and video Output is text. |
| Reasoning | low · medium · xhigh Thinking is on by default; xhigh is the default effort. |
| Access | Token Plan only No pay-as-you-go route. Singapore region. |
| API shape | OpenAI + Anthropic compatible Chat Completions, Responses and Messages protocols. |
alibabacloud.com/help/en/model-studio/qwen4-max-preview; token-plan-personal-overview Verified 2026-11-13 Preview dates and alias: Alibaba model pageToken Plan scope and prices: Alibaba Token Plan overview The request shape
The model uses the dedicated Token Plan base URL, not Alibaba's standard pay-as-you-go endpoint. The model ID and alias both resolve, but billing records the alias.
curl https://token-plan.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1/chat/completions \
  -H "Authorization: Bearer $QWEN_TOKEN_PLAN_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "qwen4-max-preview",
    "messages": [{"role": "user", "content": "Inspect this repository plan."}],
    "reasoning_effort": "xhigh"
  }'
The exact protocol path depends on the OpenAI-compatible, Responses or Anthropic Messages route. Use the Token Plan guide for the protocol you actually call; the model ID and base host are the parts that are easy to get wrong.
Three API behaviours to test before writing an integration
| Behaviour | Why it matters | What to change |
|---|---|---|
| Thinking is on by default | Reasoning consumes the same completion budget as the visible answer. | Use reasoning_effort to set the thinking level; do not combine it with a separate thinking-budget parameter. |
| max_tokens is now a combined budget | A limit sized for the answer alone can truncate a long reasoning trace. | Raise the limit deliberately and measure the total output, not just the rendered answer. |
| Preserved thinking changes multi-turn code | Chat Completions preserves reasoning by default in the preview. | Return prior reasoning in the assistant message's reasoning_content field; do not concatenate it into content. |
How access works
Token Plan Personal Edition is a Credits subscription available in Singapore. The listed 13 November prices range from $6 per month for 20,000 Credits to $43 per month for 200,000 Credits. A limited-time new-user price cuts the Lite and Essential plans to $3 and $5; current preview usage is also running at 20% of the standard Credits rate, with a further 60% off during the 22:00–08:00 UTC+8 window.
| Plan | Monthly price | Credits | Concurrent agents |
|---|---|---|---|
| Lite | $6 · intro $3 | 20,000 | 1–2 |
| Essential | $10 · intro $5 | 45,000 | 2–3 |
| Standard | $18 | 80,000 | 3–4 |
| Pro | $43 | 200,000 | 6–8 |
Token Plan Personal Edition, read 2026-11-13 Official plan and scope →
The important limit is not the lowest subscription price. It is the permitted use: interactive calls inside coding or agent tools. A custom product backend, cron job or batch pipeline is outside the stated Personal Edition scope, even if the same API key technically works. Test on the supported surface or ask Alibaba for the appropriate commercial route.
What the benchmark record says — and does not
Alibaba's model page is a capability and access document, not a benchmark report. It does not publish a comparable score table for Qwen4-Max-Preview. Third-party pages already repeat early benchmark claims, but those claims are not a substitute for a model card, a harness description or a reproducible evaluation.
That makes the page's useful benchmark advice simple: do not buy the subscription because a screenshot says a score is high. Use the two-week window to run a small, repeatable evaluation on the tasks the model is supposed to win. A preview with a known endpoint and a known expiry is a good environment for exactly that kind of test.
What to test before the preview closes
- A repository task with a real output limit. Give it a multi-file change and measure whether the combined thinking-plus-answer budget produces a usable patch without truncation.
- A video or screenshot question with a checkable answer. The input claim includes images and video; test the part you actually need rather than a generic “describe this image” prompt.
- A structured-output contract. Ask for JSON Schema output and validate it locally. A protocol compatibility claim does not guarantee your particular schema.
- One week of interactive work. Track Credits consumed, wall time and failed requests. Because the plan is subscription-based, the useful unit is cost per completed task, not the headline price per token.
What happens after 25 November
The official answer is that the preview model is retired. A permanent Qwen4 launch may follow with different pricing, a different model ID or different limits; the current page cannot promise any of those. If a durable Qwen4 model appears, this page should point to it and keep the preview facts as the dated record. If it does not, the page remains useful as an explanation of a two-week release that never became a production endpoint.
For now, the safe move is to keep the preview out of the critical path. Run the evaluation, record the date and model ID, and write down what changes if the endpoint disappears.
Qwen4-Max-Preview FAQ
What is Qwen4-Max-Preview?
Qwen4-Max-Preview is Alibaba's time-limited flagship Qwen model, released in preview on 11 November 2026. It accepts text, images and video, supports deep reasoning, tool calling, web search and structured outputs, and offers a 1M-token context window with up to 393,216 output tokens shared between thinking and the final answer.
Can I call Qwen4-Max-Preview with pay-as-you-go billing?
No. Alibaba says the preview is available through Token Plan only and explicitly does not support pay-as-you-go access. Token Plan Personal Edition uses monthly Credits and is available in the Singapore region.
When does Qwen4-Max-Preview end?
The official preview window is 10:00 on 11 November 2026 through 24:00 on 25 November 2026, UTC+8. Alibaba says no changes will be made during that period and the model will be retired when it ends.
Is qwen4.0-max-preview the same model?
Yes. Alibaba lists qwen4.0-max-preview as an alias of qwen4-max-preview. Both IDs can be used, while billing records uniformly show qwen4.0-max-preview.
How much does Token Plan cost?
At the 13 November reading, Token Plan Personal Edition starts at $6 per month for 20,000 Credits, with a $3 limited-time new-user price through 30 November 2026. The other tiers are $10 / 45,000 Credits, $18 / 80,000 Credits and $43 / 200,000 Credits. Qwen4-Max-Preview currently consumes 20% of the standard Credits rate in the promotion, with an additional 60% off between 22:00 and 08:00 UTC+8.
Can I use the Token Plan API in a production app or automation script?
Alibaba's Token Plan terms say the Personal Edition is for interactive use inside coding and agent tools such as Claude Code, Cursor, Qwen Code, Qoder and OpenClaw. It explicitly must not be used for automation scripts, custom application backends or non-interactive batch calls. Treat a production integration as a different product decision, not a cheaper way to call the preview.
Does Qwen4-Max-Preview support OpenAI and Anthropic APIs?
Yes. Alibaba says it is compatible with OpenAI Chat Completions, OpenAI Responses and Anthropic Messages APIs. The preview uses the dedicated Token Plan base URL https://token-plan.ap-southeast-1.maas.aliyuncs.com and the model ID qwen4-max-preview.
What happens to the token limit when thinking is enabled?
Thinking is on by default. Starting with qwen4-max-preview, max_tokens is equivalent to max_completion_tokens in the OpenAI Chat Completions API and covers both thinking and the final answer. A limit originally sized only for the visible answer can therefore truncate output.
Is Qwen4-Max-Preview the same as Qwen4-27B?
No. Qwen4-27B is a separate name that appears in community discussion around the Qwen4 family. Alibaba's Qwen organisation had not published an official Qwen4-27B model record when this page was read, so this page does not treat it as a released model or infer its specs from the preview.
Open the official model page Browse the OpenRouter directory