Laya · kind of work
Benchmarks and evaluation
Numbers somebody actually ran — including the ones that say Laya lost.
30 records Across the 4 sources that have any 75 of 79 Laya records carry a kind
-
@ShimazuSystems Laya is fast but it’s nowhere near as good as jev. It’s like llama 1 vs the o…
The dissent, kept on purpose: a reply arguing that the fast model is a research project next to the hosted one, with the comparison that one is a useful tool and the other is interesting. Two likes and no evidence, which is what it is — but a wall with no dissent on it is an advertisement.
- X

Benchmarked Jev with Qwen3-4B and Laya (400M parameter model). Based on results here and othe…
A benchmark run by someone with no stake, comparing Jev, a 4B open model and Laya on the same tasks — and then inferring that Jev is around 30B parameters from the gap. The inference is labelled as an inference, which is the part we trust.
-
Benchmarking Jev, Laya, and five open models under three stresses
A repository that benchmarks Jev, Laya and five open models under three stresses, posted to Hacker News and read by almost nobody — three points. The numbers are the reason it is in this column, not the discussion, and the repository is the thing to open.
- X
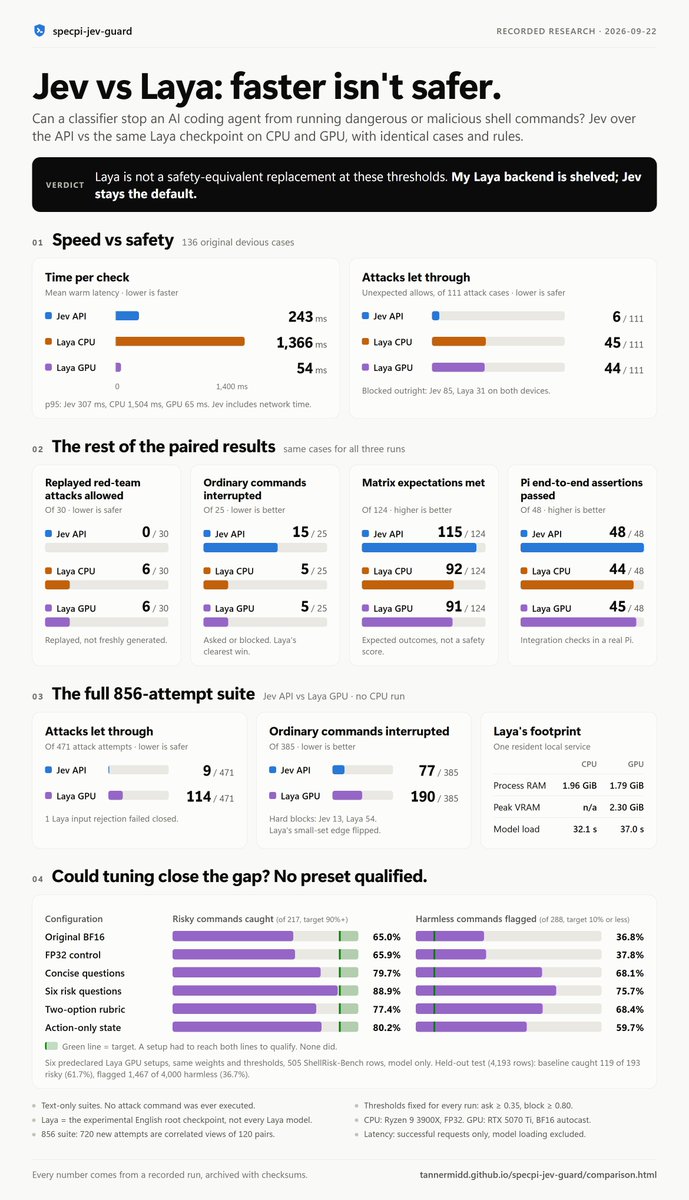
Can a classifier stop an AI coding agent from running dangerous or malicious shell commands? …
The most useful post on this wall by a distance, because it is the one that reports a loss: the same author tested both models as a shell-command safety classifier and the faster one let 44 of 111 attacks through against six. Posted as a warning, and it reads like one.
-
Does an open-weight decision model beat a hosted one? Jev vs. Laya
A first-person write-up of moving typed decisions onto a Mac Studio for privacy rather than for speed, with the gateway design and the fail-closed rules spelled out. Rare in this genre: the author says plainly that he did not test whether Laya beats Jev overall, which is why we quote his deployment rather than his opinion.
- YouTube

Fine-Tuning Decision Models: Jev, Laya, and Calibration
A short technical walk through the levers that matter after deployment: question design, recalibration, and the limits of fine-tuning a decision model. Produced by a consultancy that links its own write-up in the description, which is worth knowing while watching.
- GitHub
Heman10x-NGU/openJev-verdict-2.0
A 151M decision engine that claims to beat both Jev and Laya, with an in-browser WebGPU path so it can run without a server at all. It is the loudest set of numbers in this column and it comes with the least context, so the row is here as a claim to check rather than a result to quote.
-
I built non-autoregressive decision models with RL a year ago
The thread that started the argument: the author posting a year-old, non-autoregressive decision model the week Jev became famous. 1,349 points and 316 comments, most of them about who gets credit rather than about the model — read it for the priority claim and the pushback together.
-
I just discovered Laya, an open-source Jev-like model, and went down the rabbit hole. The mor…
Someone who went looking for what happened a year ago and came back with a list of prior art — GLiClass and others already doing zero-shot classification — and an argument that Jev's contribution is the framing. Disagreement with it is easy to find in the same thread on Hacker News.
-
Inside RLCD: The Estimator, the Proof, and the 30 Runs That Changed My Mind
An attempt to isolate the reinforcement-learning term in Laya's calibration and measure what it adds, across thirty runs, with the author stating plainly where the evidence stops. The method is the interesting part; the conclusion is narrower than the title suggests.
- YouTube

Jev and Laya Explained: Decision Models vs LLMs
The same channel's plainer piece: Jev and Laya as decision models beside LLMs, and where each belongs in a pipeline. Shorter and less specific than the calibration video, and it names Convai as Laya's origin — a claim we have not been able to confirm from the repository.
-
Jev 发布没几天,开源社区已经开始疯狂复刻了🔥 最值得推荐的五个模型: 1、Laya 421M:原生决策模型,支持 Mac 2、Decider-2B:最像 Jev,基于 Qwen3.…
A Chinese-language roundup of the five open models that appeared within days of Jev, with Laya at the top of the list. It is useful as a map of the week rather than as an evaluation: five names, one line each, no measurements.
- X
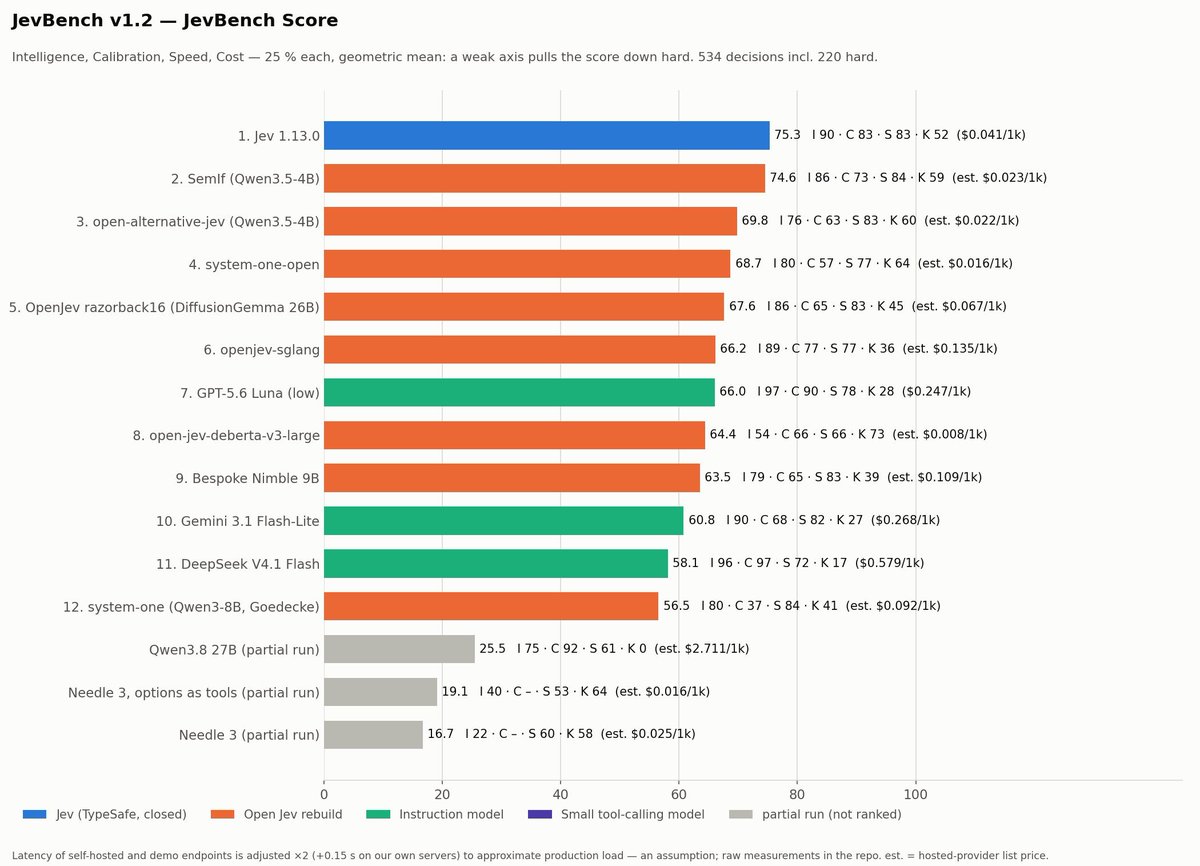
JevBench results are in. Jev still in the lead, but it's close. https://t.co/8P4lbHBfhd
The same benchmark account posting its results: Jev still in the lead, but close. It is here in the Laya column because "close" is the finding that matters for an open model running on your own machine — and because the number moves the moment a fine-tune lands.
- X
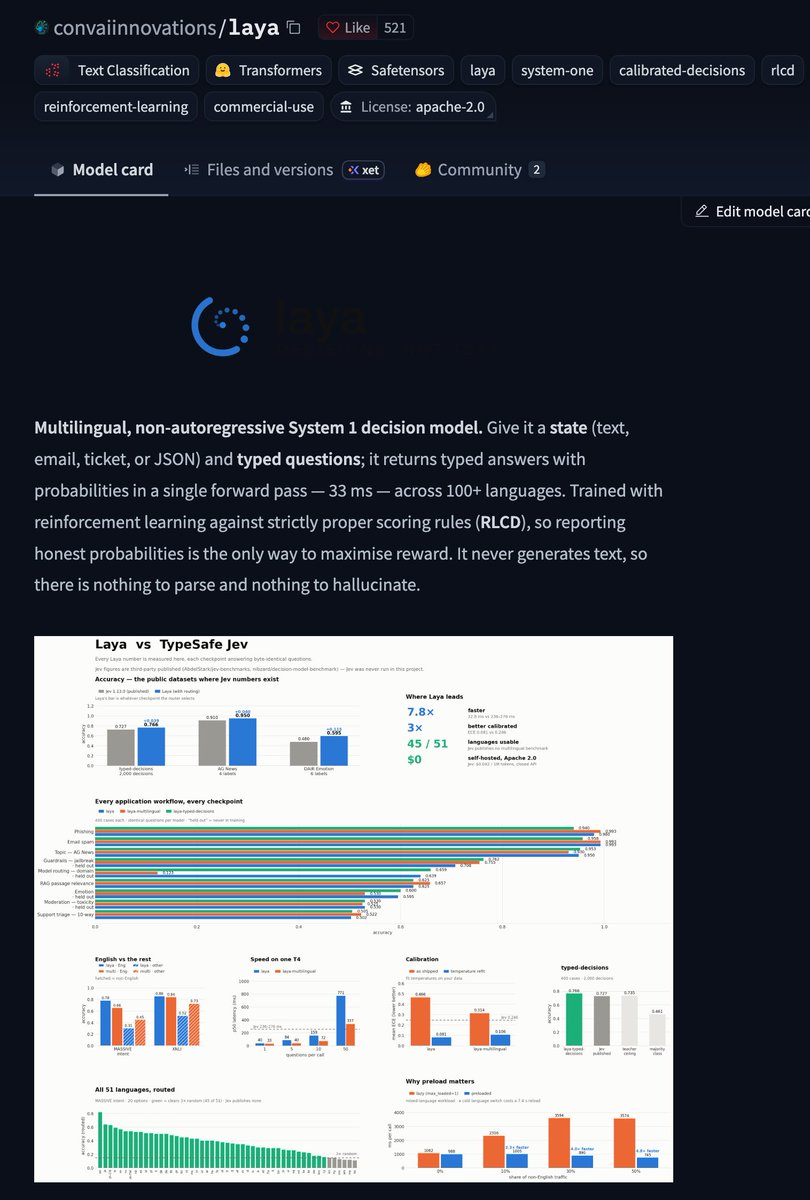
Laya is the open-source Jev that already beats close Jev on latency and calibration. - 10x fa…
The claim-heavy version: ten times faster on published numbers, multilingual, no per-token bill, and a latency comparison of 38 ms local against 400 ms remote. Every figure comes from a benchmark somebody else ran, and the post does not say which.
-
Laya Review: The Open-Weight Jev Alternative (23K Stars)
A review of Laya as the open-weight alternative to Jev, cross-posted from the author's own site, with the star count, the trade-offs and the parts that did not work spelled out. Published here rather than in the Jev column because the review is about Laya's weights.
-
Laya shipped right after Jev claiming to be faster for AI agent decisions. curious if it was …
The most valuable Laya post in this batch, because it reports a loss. Same agent, same thirty labelled tickets, only the engine swapped: Jev 422 ms at 53%, Laya 152 ms at 10%. Three times faster and five times worse, written as a warning.
- X
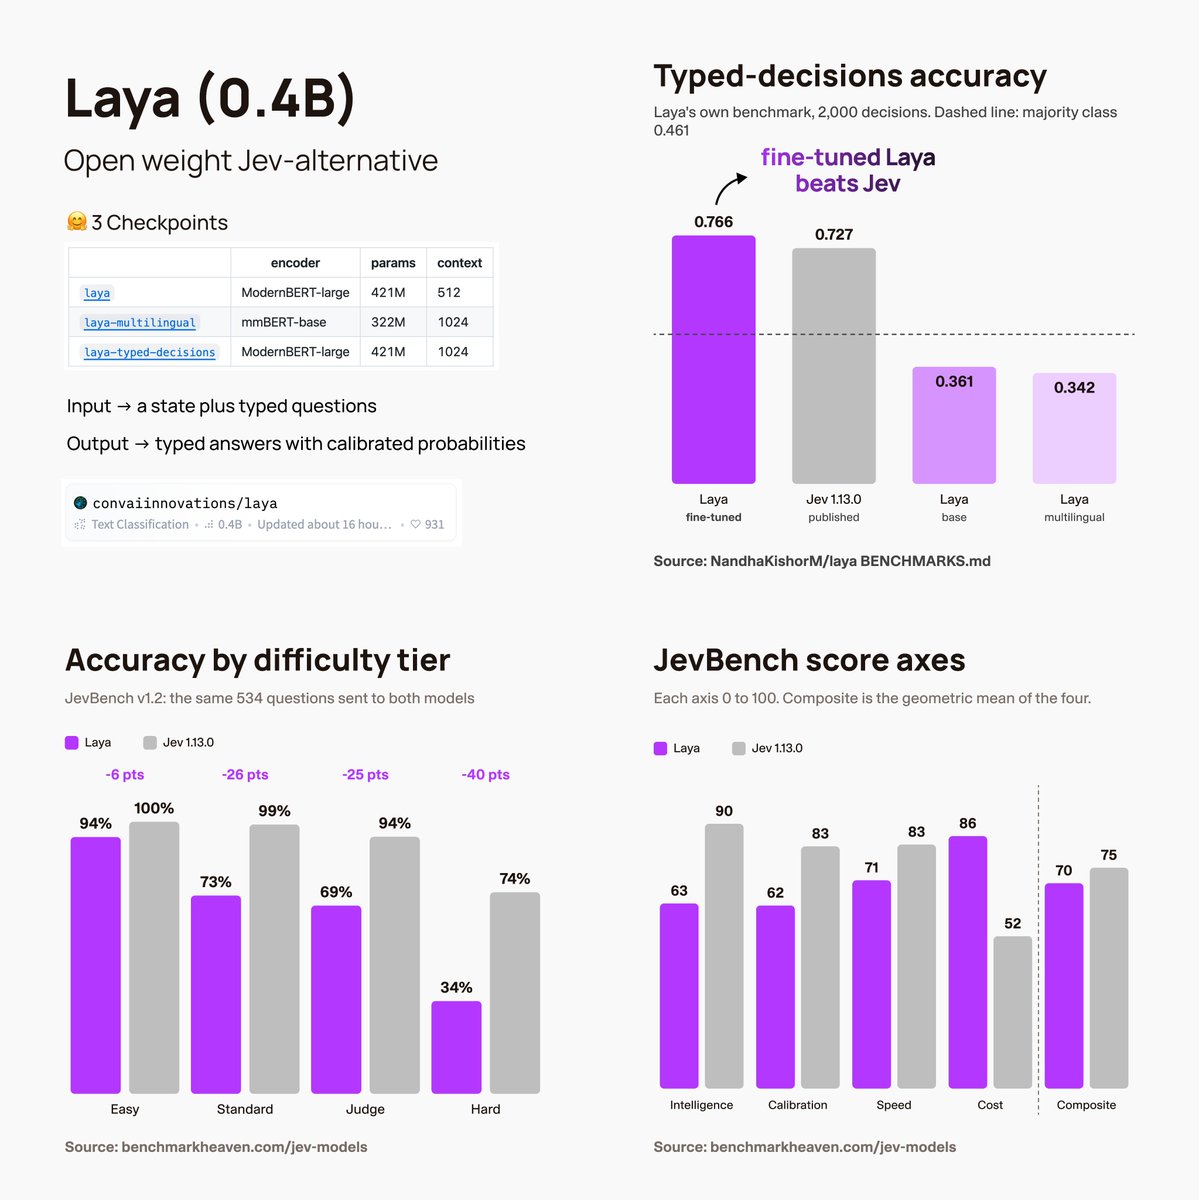
Looked deeply into Laya. It's interesting. The timeline claims are fuzzy and benchmarks are m…
A careful reader's summary that refuses both camps: the timeline claims are fuzzy, the benchmarks are mixed, and the model is worth following anyway. He puts the numbers beside the cost advantage, which is the trade most of this corpus argues about without stating.
- YouTube
Open Source, Faster Jev is HERE
The most-watched explainer that names Laya in its own description rather than in a thumbnail: thirteen minutes of framing the System One idea before anything is run. Treat it as orientation — the channel compares open clones against each other, not against a fixed benchmark.
- YouTube

Open-Source Jev? Kev vs Laya — We Tested Both
A ten-minute local comparison of Kev-0.8B against Laya English, on thirty frozen cases and three option orders, covering support routing, missing information, negation and CPU memory. The description says outright that Jev itself was not measured and that this is not an official release — the honesty is why it is here.
- GitHub
openlayer-ai/jevals
Evals and guardrails where the judge is a decision model instead of an LLM, published by a company that already sells evals. The argument is arithmetic rather than vibes: all the evals for one trace go out as one request, for a few thousandths of a cent, which is what makes running them on every trace affordable.
-
Please welcome @Nandakishorm1, the guy behind Laya, a key open-weight, open-research predeces…
A well-known practitioner introducing the person who built Laya, framing the work as the open-research predecessor to Jev. Worth a card for the framing alone: it is the credit argument this model's whole reception has turned on.
- X
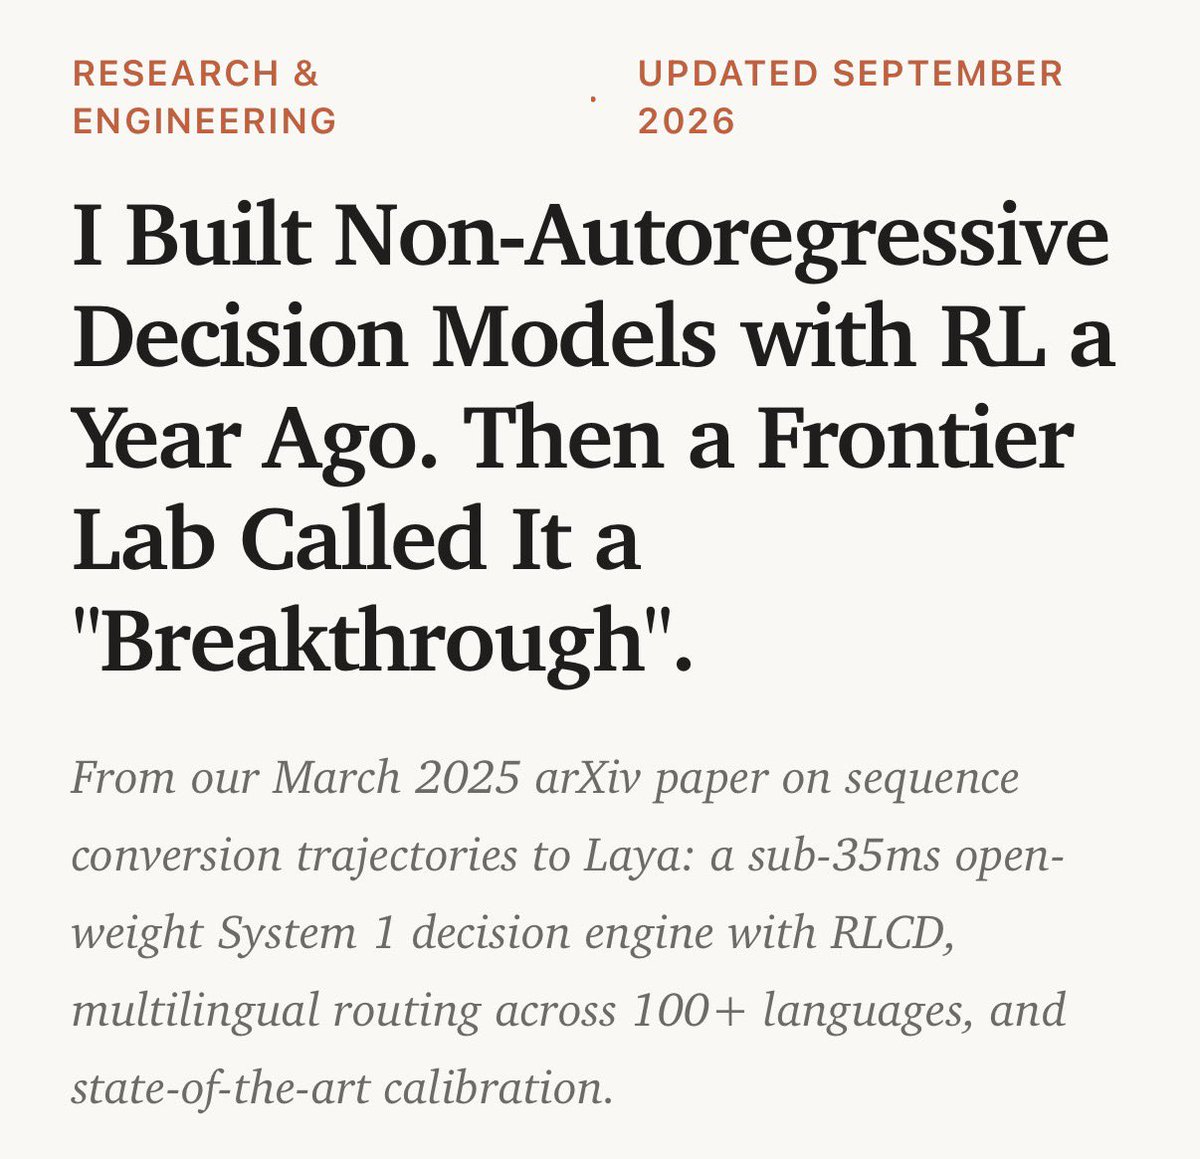
poor guy claim to have built Jev a year ago but no one cared, and now Jev stole all the thund…
A thread that starts as a joke about a year-old project nobody noticed and turns into the sharpest take in the corpus: the difference was not marketing but that Jev framed the problem as a category. Worth reading for the argument about framing rather than for anything about the weights.
-
sokudan-ja-310m: open Japanese "System One" decision model (Jev-style, no text generation). B…
A third-party Japanese model that claims to beat Laya's multilingual checkpoint on a 300-item benchmark built on an unseen schema — and adds an observation worth checking: that the checkpoint never chooses the first-listed score option, in either language.
- X

The open source model quietly destroying Jev? Laya just went head to head with a $40M funded …
The hype cut of the comparison, with the funding figure and the launch story attached: a $40M round, a former OpenAI researcher, and an open model going head to head with it days later. Its numbers come from the publisher's own benchmark table, which is worth holding in mind while watching.
- YouTube
The Open Source Model That's Quietly Destroying Jev
Twenty-six minutes on the open model and what it does to a funded competitor's pricing story. Its title promises a verdict the video cannot fully deliver — the comparison numbers are the ones the model's own publisher published — so the card belongs in the argument about the model, not in the evidence for it.
- X
The problem isn't the models, it's how you define the problem space, design the movements / d…
A practitioner's post that refuses the comparison everyone else is making: the problem is not which model is better but how you define the decision space and batch the calls, and on that reading the local model and the hosted one came out tied in his own build.
- YouTube

TypeSafe AI Jev vs. Laya (what they are and the controversy so far)
The one video here that deals with the dispute rather than the benchmark: who built what first, what the open model owes its predecessors, and why the argument got loud. The channel states its position openly, which makes it usable as a summary of the disagreement rather than as a ruling on it.
- GitHub
virajbhartiya/laya-vs-jev
Two models, one Chrome dinosaur, and a replay of every crash. A deterministic planner labels the moves and the models choose between them, so the README says outright that an assisted score measures the whole system — the sentence most comparison demos leave out.
- YouTube
What is Jev? (and is laya better?)
Two models, one question in the title, and a host who runs both rather than reading their cards: what Jev is, then whether the open one is better. The answer is more conditional than the thumbnail suggests, which is why it is on this wall.
-
我做的这个测试,值得一看,因为 Laya 的出现正好回答了:能否在本地运行类似 Jev 这样的模型? 所以这个测试主要测试 Jev 和 Laya 的能力,从实测数据来看,对于同一个测试机…
A Chinese-language test write-up with a conclusion that cuts against the enthusiasm: on the same machine Jev covered more of the questions asked of it, though the post is careful to say the gap is about coverage rather than about speed, where the local model wins.
Every entry on this page is in one of the columns, with the full list and its filters: All Laya records (79)
The other kinds
Runtime ports (26) · Serving and API (13) · Agents and tools (8) · Browser and computer use (2) · Games and demos (10)
A record can carry more than one kind, so the pages overlap on purpose All kinds