Laya · kind of work
Runtime ports
Getting the weights onto someone else's hardware: MLX on a Mac, Core ML on the Neural Engine, ggml in C++, candle in Rust, ONNX in Node.
23 records Across the 4 sources that have any 54 of 55 Laya records carry a kind
- X

⚡️ 𝗟𝗮𝘆𝗮 𝗢𝗽𝗲𝗻 𝗦𝗼𝘂𝗿𝗰𝗲 𝗗𝗲𝗰𝗶𝘀𝗶𝗼𝗻 𝗠𝗼𝗱𝗲𝗹 𝗖𝘂𝘁𝘀 𝗜𝗻𝗳𝗲𝗿𝗲𝗻𝗰𝗲 𝗟…
The 33 ms number with the mechanism attached: bidirectional encoders, a calibrated probability instead of tokens, three primitives. A promotional account's summary, but it states the architecture correctly, which is more than most of the summaries here manage.
- GitHub
afshinm/laya-mps
PyTorch's Metal backend instead of MLX or Core ML, and the row that treats memory as the constraint rather than latency: about 2.1 GiB in the fast mode, and a slower 0.74 GiB mode for machines that cannot spare it. The Pong demo renders the response time on the frame, so the number in the README is visible while it runs.
- GitHub
alvarobartt/sys1
A Rust server for the System One protocol: candle underneath, dynamic batching by token count, CPU, CUDA and Metal backends. The headline number comes with its hardware attached — about 14 ms per query on an RTX Pro 6000 — which is more than most rows in this column manage.
- GitHub
Heman10x-NGU/openJev-verdict-2.0
A 151M decision engine that claims to beat both Jev and Laya, with an in-browser WebGPU path so it can run without a server at all. It is the loudest set of numbers in this column and it comes with the least context, so the row is here as a claim to check rather than a result to quote.
- X

Jev is cool. So is it's OSS companion, Laya. The Latest Cool Thing In AI™ tends to get a lot …
A patient explainer for readers who have heard the name and cannot say what it does: how a decision model differs from a chat model, why the output has no prose to parse, and what that changes about cost. Posted by someone with no stake in either project, which is why it is near the top of this wall.
- X
Jev just got an open-source rival and it's fast as f**k Convai Innovations dropped Laya - an …
The licence, the parameter count, the backbone and the per-query latency, in one screen — a rare post in this corpus that puts the Apache-2.0 line and the speed claim in the same paragraph, which is what a reader deciding whether to adopt it actually needs.
- YouTube

Laya : Bye TypeSafe Jev AI
Six minutes, and the fastest of these videos to get to the point: the package, the weights, the three question types, done. Useful precisely because it does not try to argue the case for the model, which the longer videos above spend most of their time on.
- YouTube

Laya Is INSANE… Open-Source AI Just Challenged Jev!
A nine-minute walkthrough aimed at people who have heard the name and not the mechanism: one forward pass, three question types, no generated text, Apache-2.0 weights. The channel's framing is enthusiastic; the parts worth keeping are the three primitives and the licence.
-
Laya on Mac M4 CoreML Offline
174 points on running Laya's smallest checkpoint on a Mac through Core ML, including the memory figure people keep quoting. The comments are more useful than the headline: several of them are people working out how far the 0.74 GB claim travels.
- X
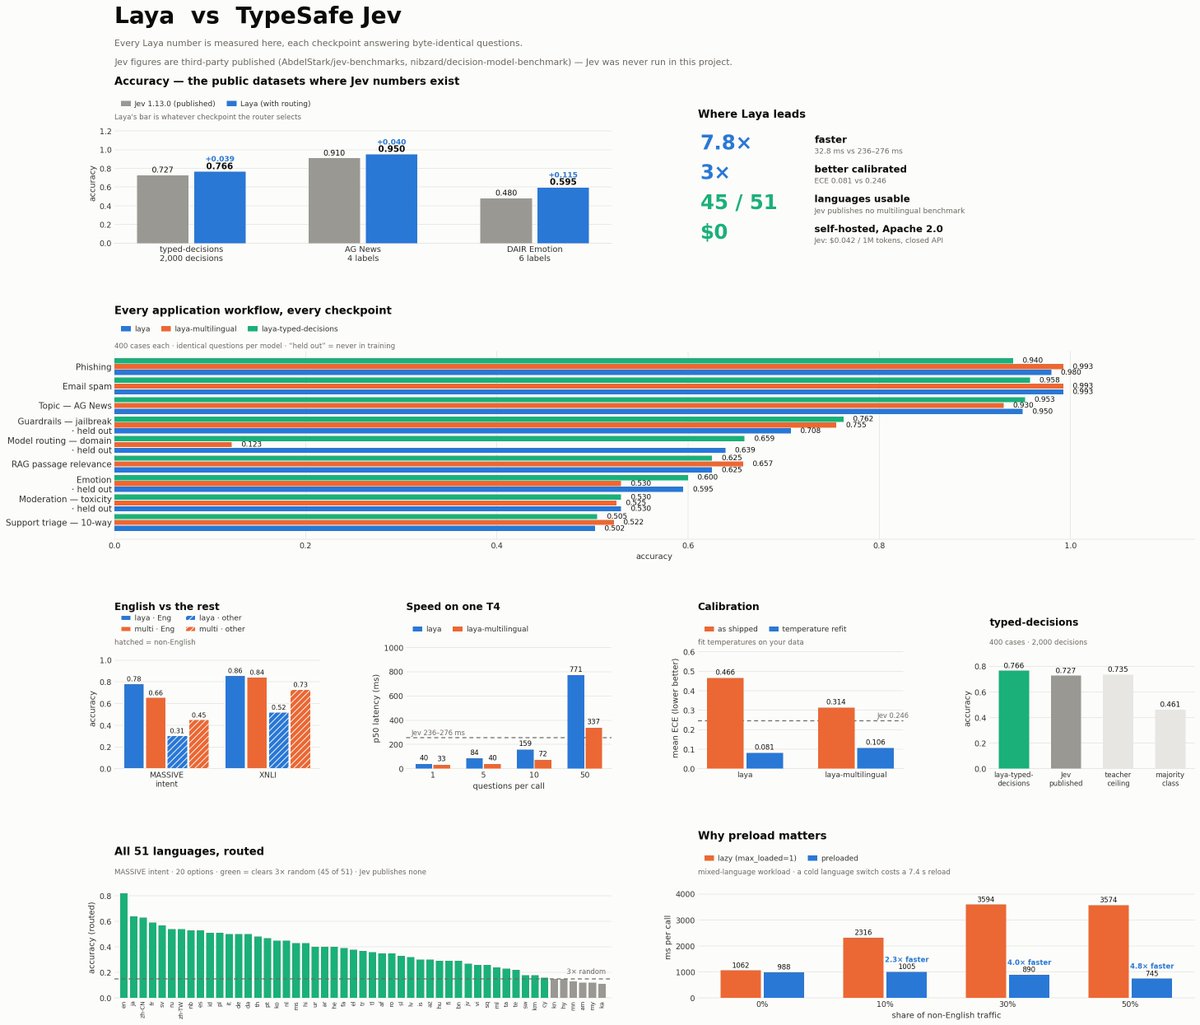
Laya 是 Convai Innovations 开源的编码器式决策引擎,用 choice、score、noul 三种提问原语对文本、邮件、工单或 JSON 提问,一次前向传播出结果,…
A Chinese-language description of the three question types that treats them as an API rather than as a novelty, which is the right level for this model. Short, technical, and it links the model card instead of a video.
- YouTube
Laya: FREE Alternative to Jev AI
A free-alternative video with a paid community behind it, and we would rather say so on the card than let a reader find out halfway through. The technical content is a competent tour of the install; the discount framing in the description is the author's business model, not a fact about the model.
- GitHub
lkarlslund/laya.cpp
ggml underneath, with CUDA, Vulkan and Core ML backends, a Jev-compatible HTTP server and request batching. It is the first port here that treats Windows as a first-class target — signed binaries rather than a build script and a paragraph of apologies, which for a C++ inference engine is the hard part.
- GitHub
mizorewww/laya-coreml
The same author's Core ML port, and the rare demo that reports energy instead of speed: 2.78× better whole-system energy per decision than compiled MLX at 4.98 ms p50. The benchmark document also says which measurements exclude terminal rendering and which do not, which is the detail that decides whether a number means anything.
- GitHub
mizorewww/laya-mlx
The port that made the numbers small: 13.4 ms median for a short English decision, 7.4 ms with the multilingual checkpoint, no PyTorch in the runtime. The README is unusually careful — it says in the caption that the latency figure is a one-question benchmark and not the frame time of the Snake loop in the GIF above it.
- X

Open sourced "Jev " that runs 50x faster own Jarvis running locally now on mac 1GB RAM. 7ms p…
The second post from the same account, and the more specific one: 7 to 14 ms per decision, under a gigabyte of memory, and a claim that a local assistant setup finished in a single pass. The memory ceiling is the number that decides whether this runs on the laptop you already own.
- YouTube

Open-Source Jev? Install Laya Locally + 3 Useful Demos
Local install plus three demos, which is the shape a reader actually needs: get the package, download the weights, then watch something work. The description points at the module names rather than at a benchmark, so it is a tutorial and we are calling it one.
- GitHub
receptron/laya
The Node path: ONNX Runtime, no Python at runtime, and about 1.7 GB of fp32 weights cached on first call. The README claims the output matches the Python reference to four decimal places — which is exactly the kind of claim a reader should re-run on their own inputs before trusting it.
- YouTube

Run a Jev-Style Model on Your Own GPU
Starts from a homely, real problem — a support-ticket classifier that costs money on every request — and runs the model on a local GPU instead. The audience is people deciding whether to keep paying an API bill, which is most of the audience for this model.
-
Show HN: Run Jev-style models locally on Mac with 0.74 GB RAM
The Show HN behind the smallest-memory claim in this column, and the reason the MPS row above exists. Three points and no comments, which is worth stating: a thread's score tells you how many people noticed, not whether the thing works.
-
Show HN: VisionLaya: Jev with Vision capabilities
A Show HN for a vision variant: images in, typed decisions out, no generated text. It is one of the first extensions of the idea past text, and the thread is short, so the card is a pointer rather than a debate.
- X
THIS IS F**KING GOLD I found Laya, which now runs natively on Apple Silicon Not via a cloud A…
A first-person account of getting the MLX port working on Apple silicon and being impressed by what does not happen: no cloud call, no PyTorch, no tokens generated one at a time. Enthusiastic, and specific about the install, which is why it made the wall.
-
You may have heard of Jev, an interesting new AI. There's an open source version, Laya. I'm b…
A distribution argument rather than a benchmark: the open weights going into a Linux distribution's hardware integration so that a decision model is always present, offline and unbilled. If the pattern holds, this is the shape it takes when it stops being news.
- X
介绍比Jev快50倍,在你设备上跑的laya-mlx! 只在你的设备上占用最高1G内存 Laya是一个开源的类似于Jev的,基于文本输出概率的分类系统 我将其移植到MLX,并且做了一些性…
The post that carried this model further than anything the vendor published: 14,000 likes for a port to MLX and a Snake game running at 60 decisions a second on a laptop. Read it for the port and the memory ceiling; the speed comparison in the text is against the hosted model's API-side numbers.
Every entry on this page is in one of the columns, with the full list and its filters: All Laya records (55)
The other kinds
Serving and API (8) · Agents and tools (6) · Browser and computer use (2) · Games and demos (9) · Benchmarks and evaluation (19)
A record can carry more than one kind, so the pages overlap on purpose All kinds