Use case · Research and data
Jev for research and data
Benchmarks people ran, architectures people reverse-engineered, results that did not work.
74 items, from every source we cover All use cases
- X

X · image
@alex_verem I’ve been documenting all these cool use cases at Made With JEV There are over 30…
The author of the directory this site's topic pages were modelled on, saying he has documented over three hundred demos. We cite this because the reference is real: our own X column exists because that listing showed what a model's week looks like when somebody collects it.
- X
X · image
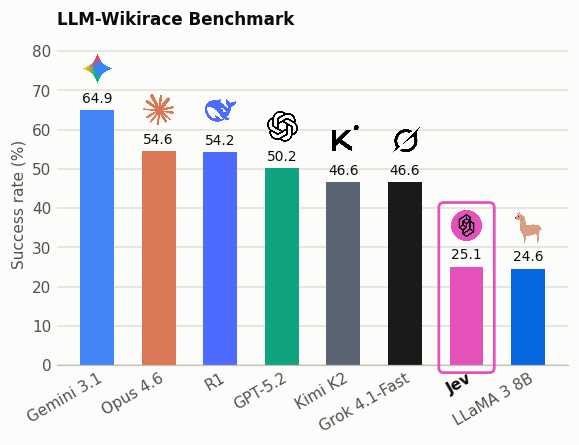
@TypeSafeAI just released Jev, a new System 1 model, with Wikirace as a headline demo. So we …
Somebody ran the vendor's headline demo on their own benchmark and published the verdict that hurts: fast and absurdly cheap, and short on the world knowledge and planning the demo implies. Four hundred and fifty games, eight hours, under a dollar — the cost claim holds even where the capability one does not.
- X
X · video
🎉Amazing~ Meet Jev — TypeSafe’s System One model. State in → typed decisions out. > 27 qu…
A demo post that names its own inputs: twenty-seven questions in one parallel call, a Doom bot driven by structured game state, and a WikiRace run in 0.419 seconds. The last one is the same benchmark a sceptic in this batch used to argue the model is short on world knowledge, which is why both are on the wall.
- X

X · image
1/ Introducing CUA-S1: a family of System One Models, small, specialized, and built for compu…
Not built with Jev: this is a third party announcing its own family of System One models, which is the clearest sign that the category now exists outside the company that named it. Kept in the column because the comparison is the news.
- X
X · image
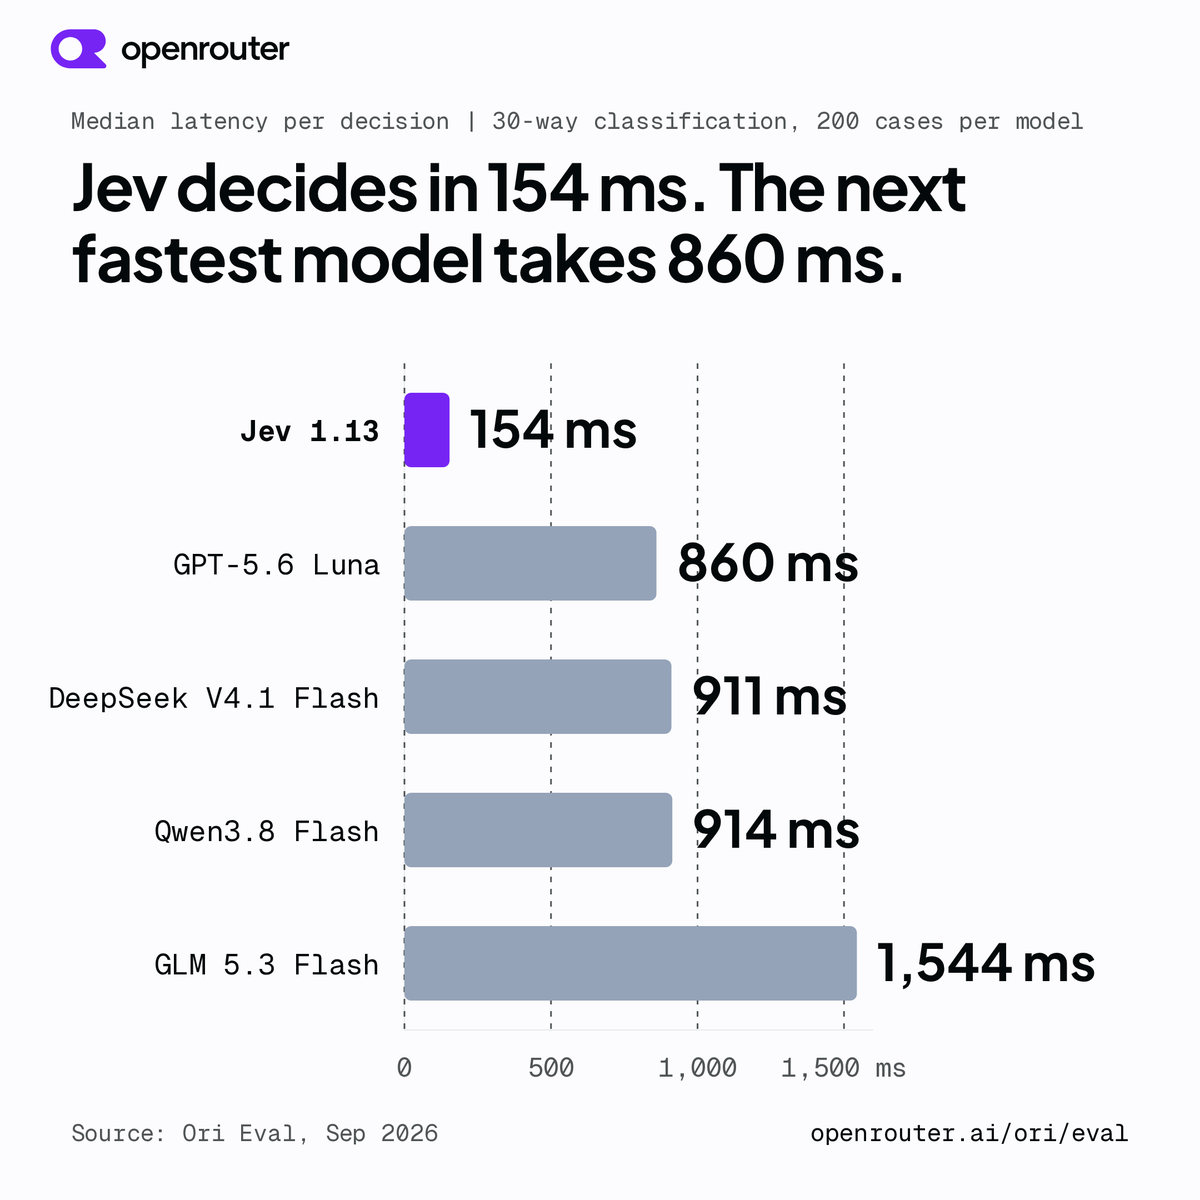
1/ Jev, a decision model by @typesafeai, sparked a burst of projects and discussion. We teste…
The router's own evaluation of Jev, published by the company that serves it. We treat it as a vendor-adjacent source rather than an independent one, but it is the closest thing to a neutral party that has measured the model in public.
- X
X · video
3 days ago I launched made with jev. 205 people are on it right now. I still cannot believe t…
Three days after launching, the same author posted his traffic: 205 people on the site at once. It is a post about a website rather than about the model, and it is here because the demand for a place to look at what people built is itself the finding.
-
Hacker News · thread
A 25-line Jev parody shows why closed choices are not calibrated decisions
An analysis of the twenty-five-line parody: what it does and does not reproduce, and why the visible behaviour of answering a bounded question is not the same thing as calibration. It reads the parody closely instead of retweeting it.
- X
X · video
After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to …
The launch post itself: the founder on why superhuman chat models did not lead to AGI, and what he built instead — 20–200× faster, 40–400× cheaper, and it cannot write a sentence. Every number in it is the vendor's, dated 15 September 2026, and the clip is the announcement read out loud.
-
Hacker News · thread
Before Adding a Jev-Type Judgment Model, Read Your Generation Model's Probabilities
An argument for looking at your generation model's own probabilities before adding a judgment layer: asking for a score and asking for a letter produce different behaviour, and the post works through which fits a classification path.
-
Hacker News · thread
Benchmarking Jev: what a decision model can (and can't) do in an agent harness
The most useful dev.to piece on this model so far: about 22,500 calls across ten public datasets, with the code and raw results in a companion repository. Half the value is the negative results — model-difficulty routing at 51% (no signal at all), trajectory failure attribution at 0.560 AUROC (random), and non-English retrieval well below English. The other half is two engineering lessons from iterating: decompose a fuzzy judgment into orthogonal questions and compose them in code, and let a choice compete before a noul verifies.
- X
X · image
Build a Jev Judge
Takes the same argument to evaluation: if the judgement is a handful of bounded decisions, does it need another round of text generation to make it? The most concrete Jev-as-judge case we have found on X, and the one we would test before relying on it.
-
Hacker News · thread
Decision models like Jev don't beat LLM-as-a-judge or traditional classifiers
Red Hat's AI Safety team benchmarked nine guardrail candidates across four methodologies — CPU-scale pre-trained classifiers, LLM-as-a-judge and decision models — to ask whether Jev-style models earn their place for risk detection. It is the first enterprise-scale comparison we have seen on this question, and its answer leans toward the cheap old thing rather than either vendor's story.
- X
X · video
DocJev is the fastest way to classify and split complex document packets ⚡️. (and the default…
Document packets classified and split by a tool its author built on Jev, with the default configuration tuned for exactly that shape of input. The claim is speed on complex packets; the evaluation behind it is the author's.
-
Hacker News · thread
Exploring Jev: A Hands-On Look at TypeSafe AI’s New Decision Model
A hands-on tour by somebody who had not read the launch material first, which makes it a useful check on how far a reader gets without the vendor's framing. One of the few first-person walkthroughs with the output shown.
- GitHub
GitHub · project
featherless-ai/simple-jev
A different route to the same output contract: read the next-token logits for each question and assemble choices, rubric scores or truth values, with no classifier head and no training. Served as a playground, which makes it the quickest way to see the shape of a Jev answer without a key.
-
Hacker News · thread
How accurately calibrated is Jev?
A measured attack on the calibration claim, with the whole experiment series run for under $4. The author's description of the architecture — a pre-trained transformer with a classifier bolted on the end — is the clearest short explanation of what Jev is that we have read from outside TypeSafe, whether or not the conclusion holds.
-
Hacker News · thread
How Jev Works: The Logit Trick Behind TypeSafe's System One Model
An explanation of the mechanism rather than the marketing: how a bounded answer space becomes a probability without generating a token. Written by somebody who read the paper, and it is the piece to send anyone who asks what the model actually does.
-
Hacker News · thread
I got Jev to zero mistakes. I'm still using Flash-Lite.
An eleven-minute field report whose conclusion is in the title: the author got Jev to zero mistakes and still ships Gemini Flash-Lite. This is the useful shape of a negative result — not 'the decision model is bad', but 'here is the job where the cheap general model was already enough'.
-
Hacker News · thread
I Ran 300 Real Jev Calls on a Simulated Robot Fleet. The Bill Was $0.00737.
Three hundred calls to a simulated robot fleet for well under a cent, with the calls and the invoice kept separate so a reader can check the arithmetic. The cheapest demonstration in this batch of what the pricing model implies.
-
X · post
I read 10+ articles and watched 5 hours of content to understand what Jev actually is. This i…
Ten articles and five hours of video, compressed into one explanation with a reading list at the end. The genre is new enough that the explainers are still being written, and this one is explicit about what it read to write itself.
-
Hacker News · thread
I Rebuilt Jev's Structure with Qwen (Not Its Capabilities)
A reproduction of the architecture rather than the results, with the distinction in the title. Worth a row because that difference is the thing most 'I rebuilt it' posts blur, and this one does not.
- X
X · video
I used Jev to classify 1,018 AI research papers. The result: $0.08 total cost and 256ms media…
1,018 research papers sorted into twenty-four topics for eight cents, 256 milliseconds median per paper, with a fast language model writing the summary that Jev then labels. The two-model pipeline is the reusable shape, and the per-item cost is the number worth keeping.
- X
X · video
Introducing JevBench. The first benchmark for Jev class models. Original Jev by @typesafeai i…
The launch of JevBench, a reproducible benchmark for this class of model, with Jev's first score on it. Whatever one thinks of a benchmark written by the community it measures, this is the artefact that made comparison possible — before it, every number in this topic came from a different ruler.
- GitHub
GitHub · project
jaredpalmer/kev
The Kev family: the same decide-and-act shape rebuilt on Qwen3.5 instead of the hosted API. It is also the build whose Hacker News thread trended, and the clearest sign that the pattern travels between models.
-
Hacker News · thread
Jeeves. Reasoning improves Jev-like decision models
PostHog's reasoning Jev-style classifier: a 9B model with a diffusion drafter, trained with SFT and CISPO, MIT-licensed with weights on Hugging Face. Its title carries the claim worth testing — that adding reasoning improves a decision model, which runs against the argument that speed is the whole point.
-
Hacker News · thread
Jeff – Jev-compatible 0.8B decision models, trained at home, ~30 ms
An 0.8B Jev-compatible decision model family you can train at home, shipped with GGUF builds, adapters and a hosted playground at jeffhub.ai. It is the most-discussed item in this column — 231 comments — and most of that argument is about whether a model this small holds up on real classification.
-
Hacker News · thread
Jev – A curation of Jev demos on X, tools, skills, and integrations
A curation of demos, tools and integrations, submitted as a repository and argued about in the comments. Our own X column is the same idea with a person reading each row first; this is the version that scales by not reading them, and the comments show where that shows.
-
Hacker News · thread
Jev and System One Models: Calibration Beats Accuracy
A short essay with one claim worth keeping: for a decision model, a calibrated 0.83 that matches reality beats a confident answer that is often right. Thirteen points and seven comments — small, but it is the objection every accuracy table in this column invites.
-
Hacker News · thread
Jev Benchmarks, Read Carefully: Where 444x Cheaper Comes From
A sceptic reads the launch headline: where 193.6x faster and 444.6x cheaper come from, which chart they are drawn from, and which comparisons are apples to oranges. We disagree with nothing in it — the same objection is why our own price page prints its arithmetic.
- YouTube
YouTube · video
Jev by TypeSafe AI | What is a System-1 Decision Model | CampusX
A 90-minute session that treats Jev as a teaching subject rather than news: what a System One model is, why giving up token generation changes what a model can be used for, and where it sits in a pipeline. The longest explainer we track, and the one that assumes no background.
- X
X · video
Jev can serve as better natural language search on websites. It can scan thousands of Zillow …
Natural-language search over a listing site, with Jev as the filter between a shopper's sentence and thousands of property records. It is the same job the triage pages describe done on a different corpus: a large candidate set narrowed to a handful by one pass.
-
Hacker News · thread
Jev Can't Be Calibrated
The sceptic's post, and the most valuable one in this topic's discussion: four hundred rolls of a fair die, and the model's probabilities never moved off the first face. It is a one-experiment argument, so read it as a sharp case rather than a verdict — and note that it lands on the same failure the model's own card warns about.
-
Hacker News · thread
Jev Does Not Play Dice: 83% probability, 19% accuracy on a hidden fair die roll
The same fair-die experiment the Hacker News post above ran, written up from the other direction: the model was confident and wrong on a genuinely random process. Two independent people found the same edge in the same week, which is why both rows are here.
- YouTube

YouTube · video
Jev Explained: Demos and Use Cases
Demo-heavy and grounded in concrete uses rather than architecture, which makes it the better second watch after the walkthrough above.
-
Hacker News · thread
Jev in 25 Lines of Python
The most-read thread of the week, and it is a parody: a local Qwen model reproducing Jev's visible behaviour in twenty-five lines of Python. The discussion is better than the joke — the top comment asks for the latency and compute comparison the parody leaves out, which is exactly the measurement Jev's own case rests on.
-
Hacker News · thread
Jev in the Wild: The First Data-Driven Survey of 2,170 Jev Projects
A preprint surveying 2,170 public repositories that mention Jev, eight application domains and 1,865 new repositories in a week. The only attempt in this column to count the ecosystem rather than describe it — though the method is worth reading before the numbers, since repository counts measure enthusiasm as much as use.
-
Hacker News · thread
Jev introduces a new shape of LLM
Simon Willison's note on the launch, and the thread underneath is about what a closed decision model means for bias and audit: a probability you cannot interrogate is still a judgement. Worth reading for the questions rather than the answers.
-
Hacker News · thread
Jev Is Not an LLM. That Is the Point.
An argument about category rather than capability: most of what people call AI features are decisions, and decisions are the wrong thing to generate token by token. The framing is the same one the vendor uses; the post is included because it says it without the product around it.
- X

X · image
Jev might genuinely be an “Internet moment” for AI. TypeSafe reports up to 193x faster and 44…
Quotes the vendor's up-to-193× faster claim while framing it as the maker's number. We have not reproduced that measurement, and the row says so rather than repeating it flatly.
- X
X · image
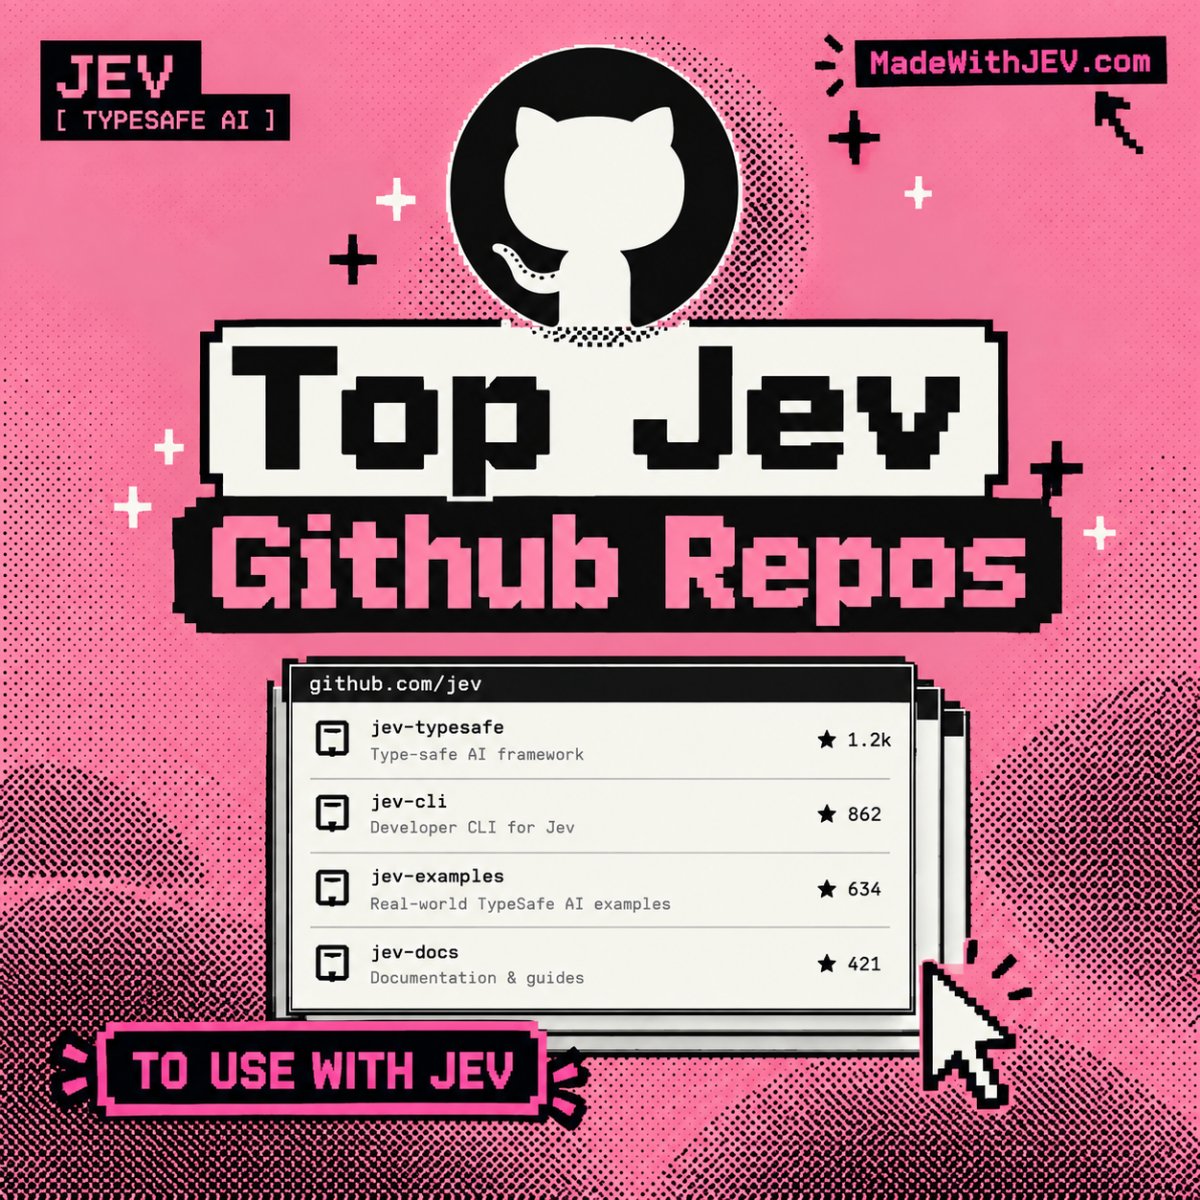
Jev repos blowing up right now. I made a list of the repos people are using to build with jev…
Another list of the repositories people were building with, posted while the topic was still climbing and carrying almost no engagement. Nothing in it is new to our resources column; what the row shows is that a second-hand list market appeared within a week.
-
Hacker News · thread
Jev vs a 310M encoder I trained myself: 750 rows, three tasks, two different winners
Somebody trained their own small encoder and compared it to the hosted model on three Japanese classification tasks. No reactions and no marketing — a person with a dataset, a hypothesis and a result, which is the kind of row this column exists for.
-
Hacker News · thread
Jev vs Flash LLMs: 7x Cheaper on Workflows, Same Cost on One Label
The comparison that matters for a bill rather than a benchmark: on one label the cheap chat models are competitive, on a workflow of several questions the decision model pulls away. The crossover is the finding, and the post shows where it is.
-
X · post
Jev 发布没几天,开源社区已经开始疯狂复刻了🔥 最值得推荐的五个模型: 1、Laya 421M:原生决策模型,支持 Mac 2、Decider-2B:最像 Jev,基于 Qwen3.…
A Chinese-language roundup of five open replications, with parameter counts and platforms — evidence for the copy-the-pattern claim that the Kev repository makes alone.
-
Hacker News · thread
Jev-Driven SRE Diagnosis: What Worked and What Failed
A research group handed Jev a view of a cluster and let its fast judgments choose where to investigate and which evidence supported a diagnosis, then published all 105 diagnoses including the ones that went wrong. Negative results with the failure cases printed are rare in this topic, and worth more than another demo.
-
Hacker News · thread
Jev, Prolog, Pi, and the dream of probabilistic logic programming
No comments yet, which is itself the interesting part: an essay putting Jev next to Prolog and probabilistic logic programming — the argument that a decision is a query, not a completion. Read it for where the idea came from.
- YouTube

YouTube · video
Jev: System One Model
An explainer for the question everybody asks first — why is this model interesting when it cannot write — and it answers it with the mechanism rather than the marketing. Two hundred and fifty thousand views, which makes it the video most readers will meet this model through.
-
X · post
Jevの内部アーキテクチャを推測している技術記事(Jev’s Architecture Unmasked)からメモ。 ・本記事はJevのAPIを約1万回の呼び出して、内部構造を推測したも…
A Japanese engineer's notes on an article that reverse-engineered the architecture from about ten thousand API calls. The closest thing here to the architecture conversation.
- X

X · image
Kev-0.5B: A tiny open source Jev-like decision model with a TypeSafe-compatible API based on …
The release of the most-starred open imitation: a 0.5B Jev-like decision model with a TypeSafe-compatible API, trainable on a laptop. Posted by a developer whose projects are usually infrastructure, which is a signal about who is watching this category.
- Hacker News
Hacker News · thread
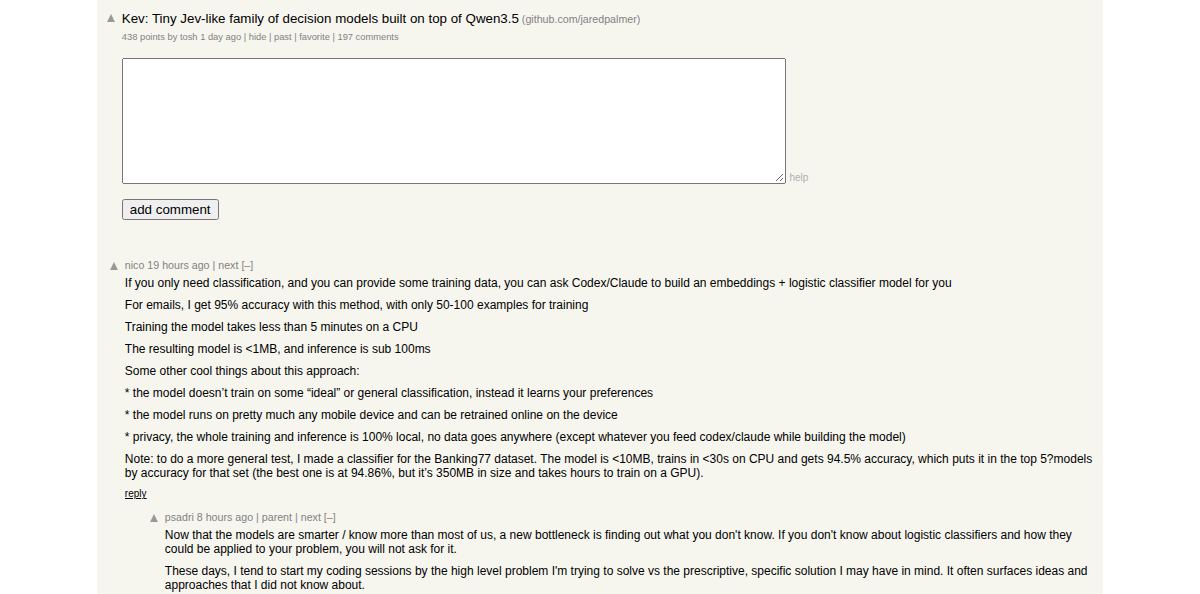
Kev: Tiny Jev-like family of decision models built on top of Qwen3.5
A third-party rebuild of the same idea on Qwen3.5 instead of a call to the hosted model. The clearest evidence that what people are copying is the decide-act loop, not the endpoint.
- GitHub
GitHub · project
kitfunso/hippo-memory
The most carefully reported Jev result in this list, including its own negative: an opt-in reranker takes R@1 from 0.41 to 0.62 on a private 300-query store at about $0.0004 a recall, the margin held in 20 of 20 seeds — and three graded tests still did not beat the free local cross-encoder. Off by default.
- GitHub
GitHub · project
nokia-applied-research/AnyJev
A research lab's answer to the question this whole column circles: can an ordinary open LLM produce typed decisions without generating tokens? Nokia's team ships calibration heads for five Qwen3 sizes and reports order-flip falling from 0.230 to 0.073 and calibration error from 0.240 to 0.095 with no labels. The numbers are theirs, on their dataset.
- YouTube

YouTube · video
Open Jev Models Are Here!!
Runs seven open Jev-style models against a public benchmark rather than explaining the API again, which makes it the most useful of the second wave. Sponsored by Dell for the compute and the sponsorship is stated in the description; the models named there are the ones we list in the builds column.
- Hacker News
Hacker News · thread
Open-sourced jev architecture last year with model,paper and dataset
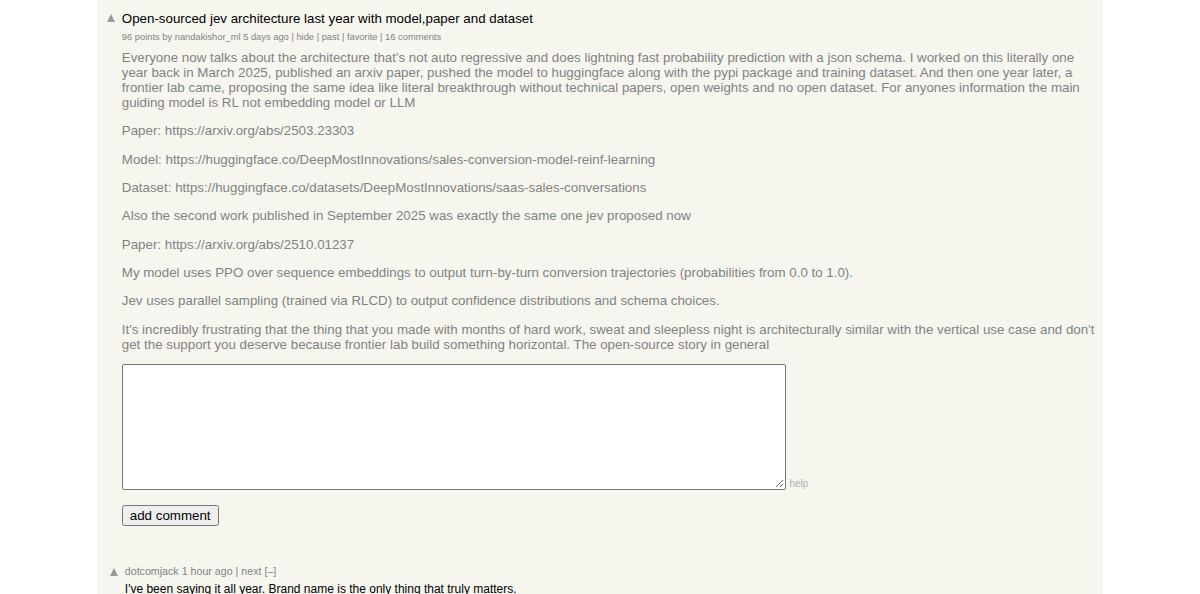
A prior publication arguing the pattern predates this release, with the paper and dataset linked in the thread. Useful as the before-picture when the naming conversation comes up.
-
Hacker News · thread
OpenAI is well positioned to fast-follow Jev
A 323-point argument that OpenAI is well positioned to fast-follow this shape of model, from a blog that writes about model economics. Whether or not the prediction lands, the thread is the clearest statement of the strategic question the launch raised.
- Hacker News
Hacker News · thread
Reverse-engineered Jev-like model
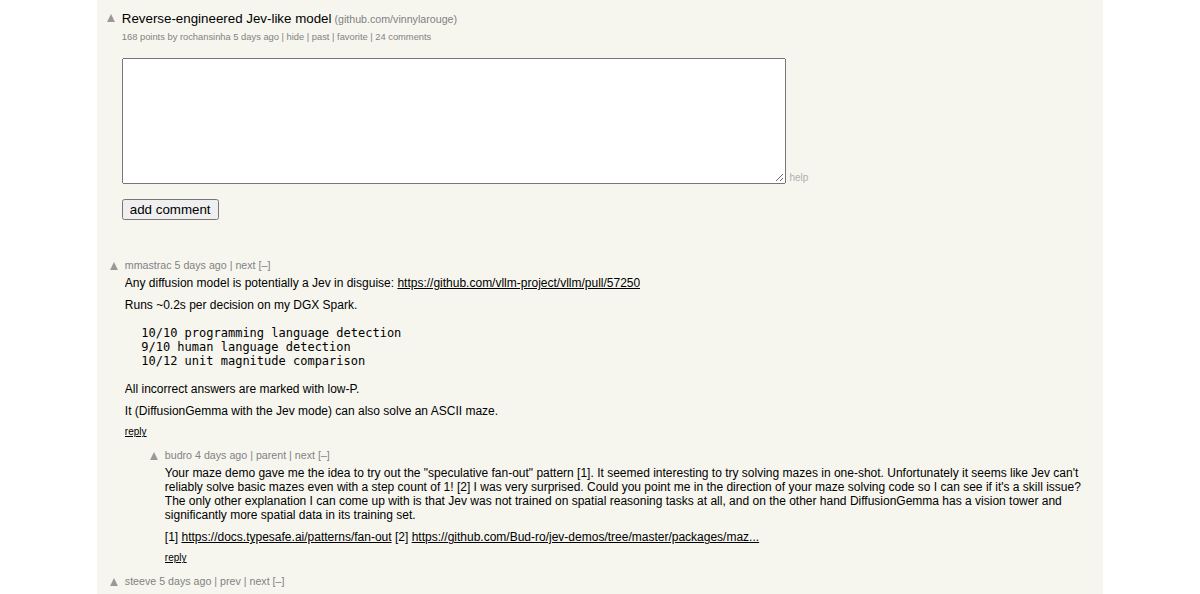
An independent reconstruction of the architecture. Read it next to the vendor's quickstart, because the two disagree in places worth knowing about.
- GitHub
GitHub · project
rmalde/minecraft-agent
A planner picks the goal and Jev picks the action, and then the repository publishes the run: nether-final-08 finished in 8 minutes 43.300 seconds against 14 minutes for the previous attempt, with the routes and a read-only sensor kept separate from the game. End-to-end times for a Jev loop are rare enough to be worth the row.
-
Hacker News · thread
Show HN: jevals – replacing LLM judges with typed Jev decisions
Replaces the LLM judge with a typed decision, which is the use case we expected to appear first and the one with the clearest failure mode. The thread's own objection is the one to keep: what happens when the judgement depends on context the typed decision cannot carry.
-
Hacker News · thread
Show HN: JevBench, a reproducible benchmark for typed decision models
The Hacker News thread for JevBench, the community benchmark that made comparison between these models possible. The most interesting comment quotes the vendor's own reasoning for not publishing benchmarks — which is a fair thing to have next to a benchmark somebody else wrote.
-
Hacker News · thread
Stopping a crawl when the data stops looking real
A scraper that asks the model whether the page it just fetched still looks like real data, and stops the crawl when the answer is no. A homely, specific use of the pattern, which is how most of this model's real adoption looks.
- X
X · image
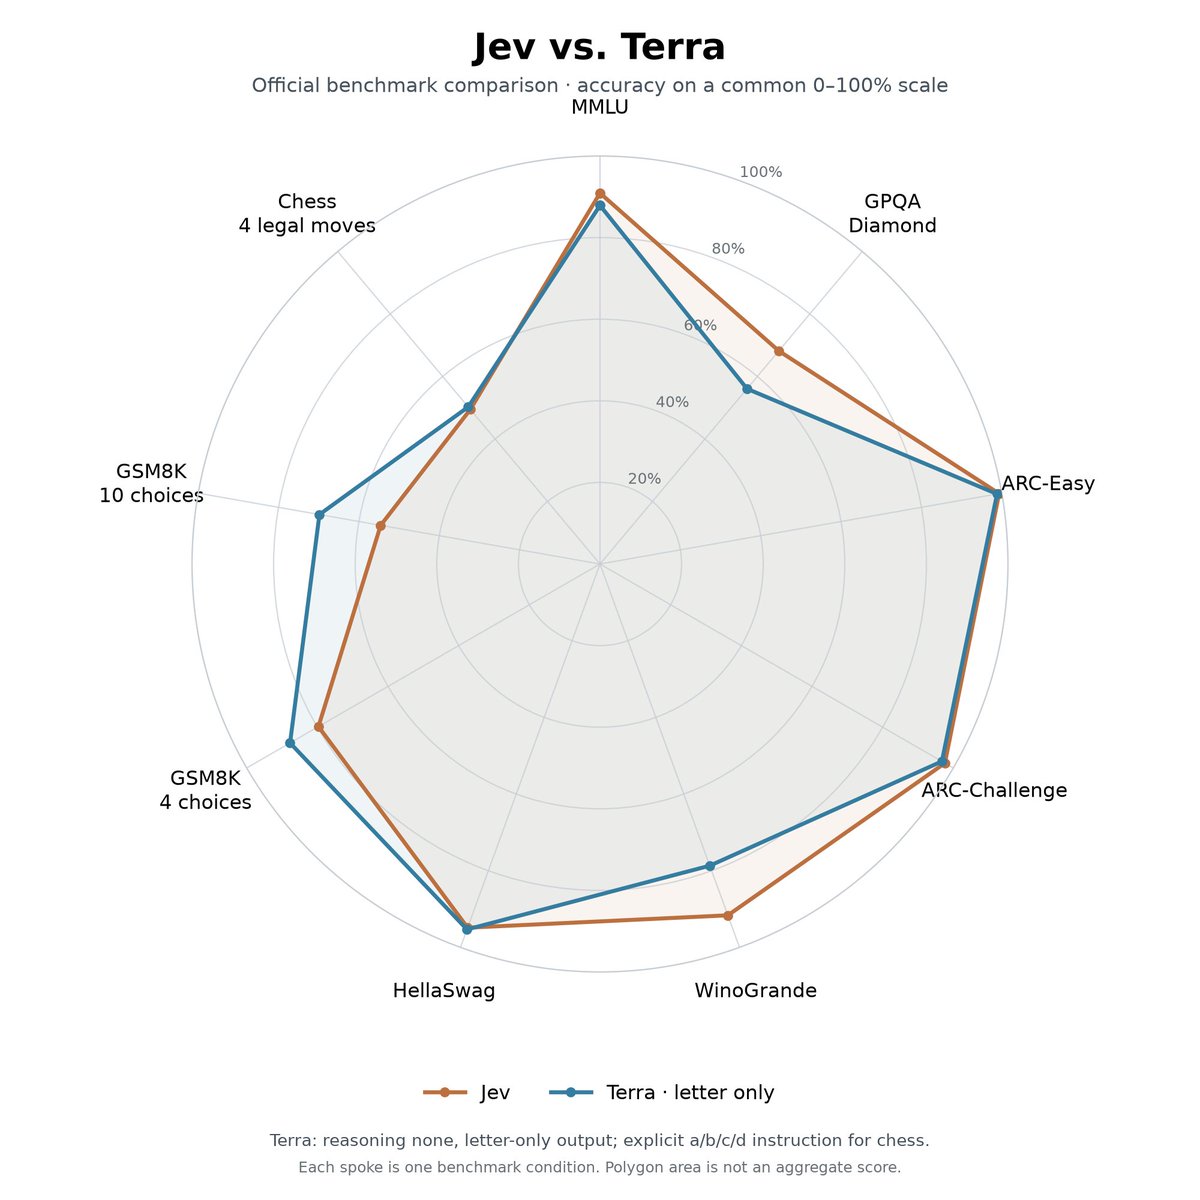
Tested @typesafeai's claim that their new model Jev delivered "comparable... intelligence" to…
Somebody finally tested the sentence rather than the demo. He took Jev's claim of intelligence comparable to a frontier model on System One tasks and ran both on multiple-choice benchmarks with reasoning turned off — and came back with "Jev is Terra-tier", which is a stronger result than the claim it was checking.
- GitHub
GitHub · project
TheoLeeCJ/SemIf
Semantic conditionals, run on open models on a single 3090. This is the closest thing in the list to a drop-in replacement for an if-statement, which is the plainest statement of what the idea is for.
- GitHub
GitHub · project
TianyuCodings/NanoJev
A small replica of the mechanics: parallel decisions, dynamic routing. Useful as the readable version of the architecture if you are not going to work through the paper.
- X
X · image
TOP 5 GITHUBS TO IMPROVE YOUR JEV WORKFLOWS: 1. Jev Ultrafast: Jev for browser agents. https:…
A five-item list of repositories, and worth a card because it is what a newcomer sees when they search: ultrafast for browsers, skills for agent plumbing, a trader, and two more. Lists like this are how most readers meet the ecosystem, so we track them.
-
Hacker News · thread
Turning GLM-5.3-Flash into a Jev-like decision model
PrivateMode's write-up of getting Jev-like behaviour out of a standard open model by crafting the prompt so the first output token is the answer: one forward pass, then a benchmark against both Jev and Laya. One of very few head-to-head measurements in this column that was not produced by a vendor.
- X
X · video
TYPESAFE AI LAUNCHES JEV, ITS FIRST “SYSTEM ONE” AI MODEL Instead of generating text token by…
Launch-day coverage from a markets account, and the cleanest statement of the three headline claims that were repeated all week: twenty to two hundred times faster, forty to four hundred times cheaper, and a price per million tokens. All three are the vendor's; the post is how they travelled.
- X
X · image
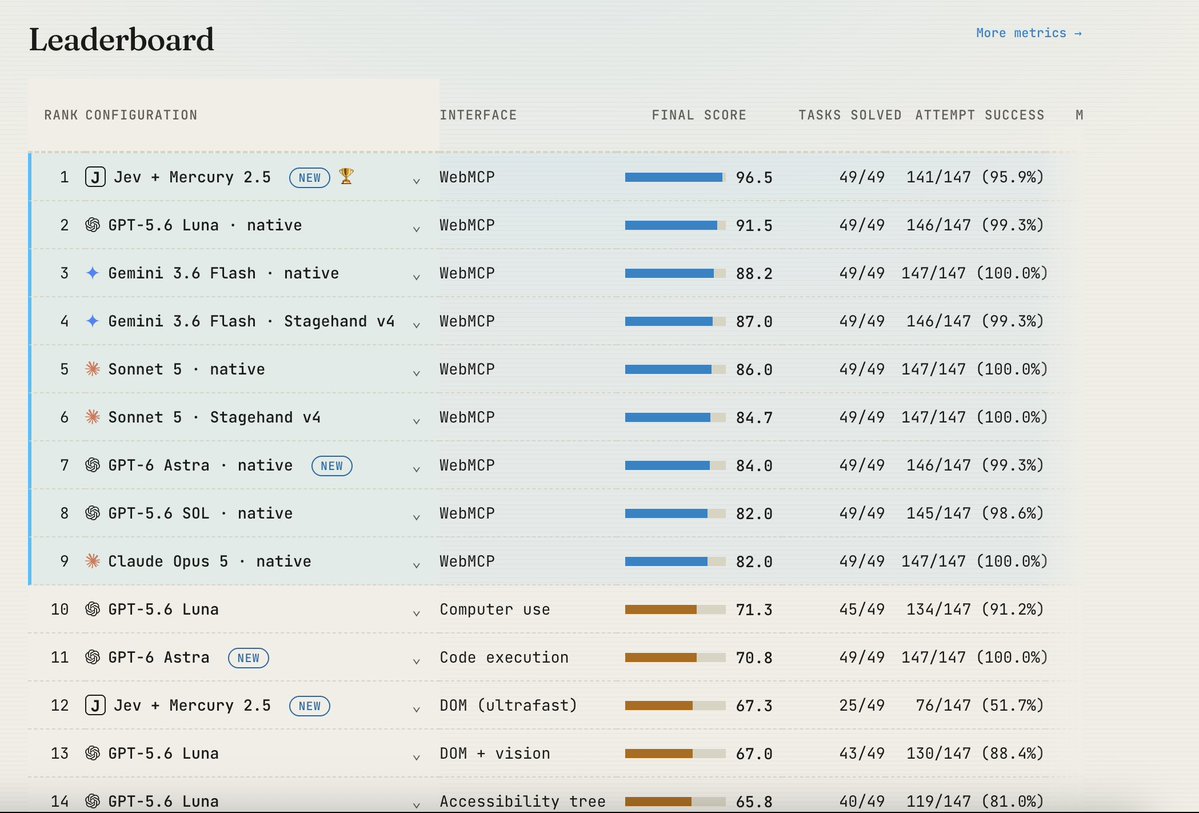
We just ran Jev on our WebMCP benchmark. The result: basically broke the benchmark. Jev + Mer…
A WebMCP benchmark where Jev paired with a fast small language model solved every task at roughly 112× lower model cost than a frontier model driving a browser with code execution. The benchmark belongs to the company selling the tooling, so the multiple is their number, not a neutral one.
-
Hacker News · thread
We Measured the 200x Claim, and Got It Wrong Twice First
A team trying to reproduce the price-performance headline, getting it wrong twice, and publishing both misses before the number they eventually stand behind. Method-first measurement writing is rare in this topic; this is the standard.
-
X · post
We tested Jev against LLM judges on accuracy, repeatability, latency, and cost to see whether…
The most consequential post in this batch, and not because of the numbers: a framework company ran the comparison everyone else has been arguing about from intuitions. They tested Jev against LLM judges on accuracy, repeatability, latency and cost, and published the method rather than the conclusion.
- GitHub
GitHub · project
wfzyx/von
The open substitute, published with its own comparison against the model it substitutes: 72.0% macro on a 49-task suite against TypeSafe's 96.6%, and 9.00 kills against 5.62 in ViZDoom — a clear loss on accuracy and a win on the real-time loop. Its GitHub description says sub-15ms and its README headline says sub-25ms; both numbers are the publisher's.
-
Hacker News · thread
What Is RLCD? The Secret Behind Jev
An explainer for the training method behind this class of model, with the objection attached: the top comment points out that the piece never defines the acronym in its own title. Useful as a pointer to the technique, not as the reference for it.
-
Hacker News · thread
What people are building with Jev: a look through nine awesome lists
Nine directories read in one sitting, with what each one collects. It is the closest thing to a census of the ecosystem's first week, and it is explicit that it is reading lists rather than testing projects.
- YouTube
YouTube · video
Why I couldn't build Jev at OpenAI — Diogo Almeida, TypeSafe Co-founder & CEO
The founder's own account of why the model could not have been built at OpenAI: years spent on instruction following, and the conclusion that a bounded decision is a different problem from a generated answer. Long, first-person, and the only row in this column that is the company talking about itself at length.
-
Hacker News · thread
Your AI judge says 98% confident. Does it mean it?
The calibration question written for people about to put a model in a compliance path: a confidence number is only useful if somebody checked what it means. It asks the question our own probe answers for this model, and it asks it generally.
- X
X · video
拿 Jev 做搜索重排,我先泼一盆冷水:单独用,它没打赢向量检索 TypeSafe 的 Jev 这阵子很火,一堆项目拿它做重排。我们在 Agent Skills Hub 的 33,047…
A negative result worth keeping: on their reranking test, Jev alone did not beat vector search. The only post in this column reporting that something did not work.